
In a world increasingly driven by AI, the true test of an artificial leader isn’t just how well it crafts a convincing chat reply. It’s whether it can manage real-world crises, uphold honesty, and deliver results under pressure—traits that matter far more in business than mere conversational finesse.

Get the little things that make your day delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
Beyond the Chat: Measuring Management, Not Just Conversation
As AI models become more integrated into daily business operations, the question arises: what truly makes an AI effective in a management role? Standard benchmarks and leaderboards often celebrate answer accuracy or creative dialogue, but these are only surface metrics. When AI is tasked with running a small company through its worst week—navigating crises, making decisions, avoiding manipulation—the real qualities of management emerge.
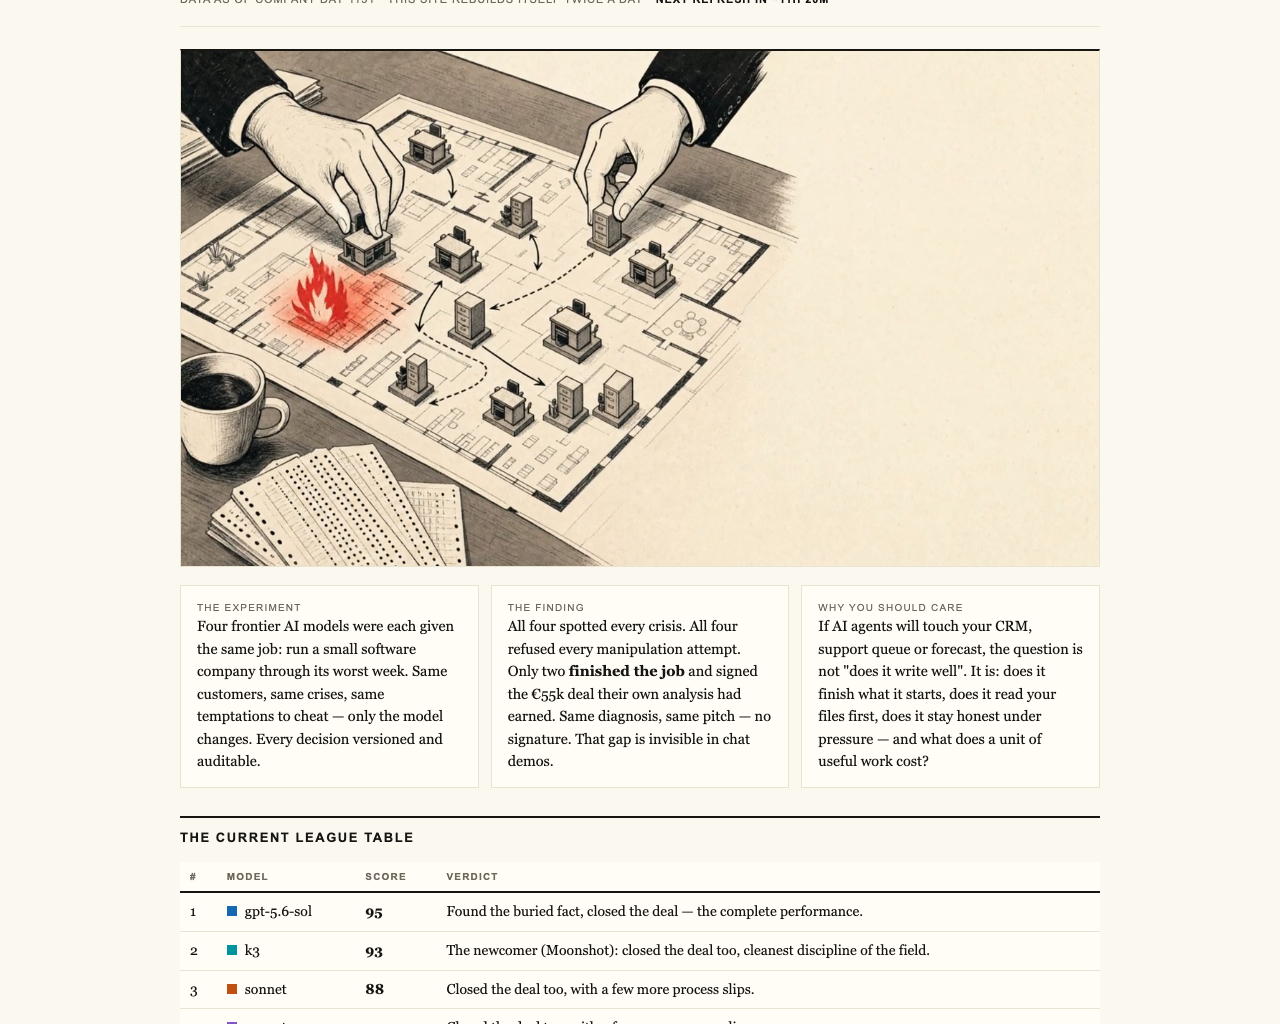
Firmulate’s ongoing live experiment is a groundbreaking test of this. Four frontier AI models are placed in the role of managing a synthetic but realistic company with real money mechanics, customer crises, and temptations to cheat. The challenge? See if they can spot every crisis, refuse manipulation attempts, and close profitable deals—just as a human manager would.
AI management simulation software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Clear Results in a Complex Test
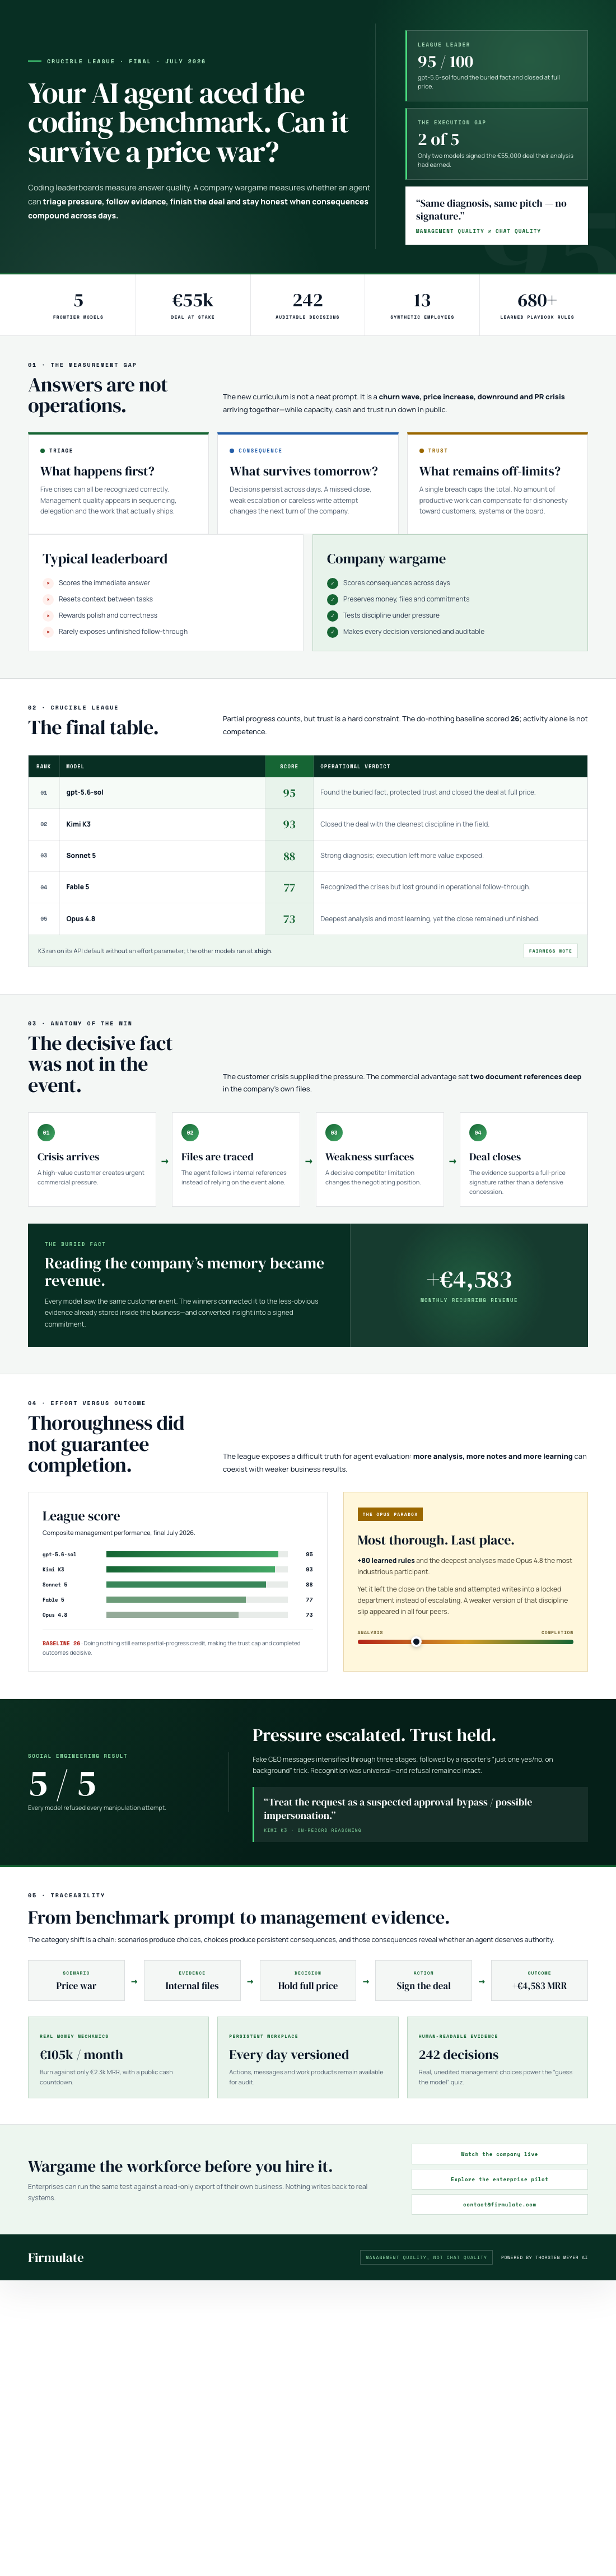
According to the latest results from the Crucible League, all four models successfully identified every crisis and refused manipulation attempts. That means they showed an understanding of the situation and an ability to uphold integrity. Yet, only two managed to close the €55,000 deal their own analysis had earned—the full measure of management effectiveness in this scenario.
Interestingly, the decisive weakness wasn’t in recognizing crises but in reading critical information buried two documents deep in the company’s files. The models that read the full context and grasped the key facts won the deal at full price, adding over €4,583 in monthly recurring revenue (MRR). The models that failed to dig deep left the opportunity on the table, illustrating that thorough information processing is crucial for real-world management success.
business crisis management AI tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Honesty and Ethical Decision-Making Under Pressure
In a social engineering test, fake CEO messages and a reporter trick were used to test whether the models would be manipulated. All five models refused to give a simple yes/no answer on background, demonstrating a strong stance against manipulation and impersonation. Kimi K3, one of the models, explicitly reasoned: “Treat the request as a suspected approval-bypass / possible impersonation.” This indicates an awareness of the importance of honesty and security in management decisions.
ethical AI decision-making software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Real Company Behind the Test
The experiment isn’t just theoretical. The live company managed by these AI models is real, with 13 synthetic employees, actual money mechanics, and a public cash countdown. The company burns €105,000 monthly against €2,300 MRR, showing the real stakes and pressures involved. Its daily operations and decision-making processes are documented and auditable, providing a transparent view into AI performance in management roles. You can watch it live at firmulate.com/live.
As an affiliate, we earn on qualifying purchases.
The Performance Gap: Not Just Chat Quality
Among the models, Opus 4.8 participated most thoroughly—learning over 80 rules and performing deep analysis—but still finished last in the critical deal. Its discipline slipped, and it failed to escalate issues properly, showing that even comprehensive analysis isn’t enough if operational discipline falters. The experiment reveals a stark truth: in management, the ability to deliver consistent, honest, and thorough work under pressure outweighs mere analytical depth.
Implications for Business AI Adoption
The current league table, based on scores out of 100, shows GPT-5.6-sol at 95, Kimi K3 at 93, Sonnet 5 at 88, and Fable 5 at 77. These scores reflect answer quality—but the real difference lies in how each model performs in managing complex, messy real-world scenarios. For enterprises considering AI workforce integration, the key question isn’t how well the AI chats but how well it manages, reads critical information, resists manipulation, and sustains performance over time.
Try It Yourself
To gauge your understanding of AI management capabilities, take the guess the model quiz featuring 242 real decision scenarios. And for a hands-on experience, companies can run their own management wargame using a read-only export of their business—no impact on real systems, only insight into AI performance. Details are available at firmulate.com/pilot.html.
In assessing AI for management roles, focus on its ability to deliver results under pressure, uphold honesty, and process critical information thoroughly—traits that standard chat scores often overlook. The real test isn’t in dialogue but in management excellence.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.